Site speed is determined by a specific, orderable set of technical factors — not a vague quality a site either has or lacks. Understanding the order they typically matter in makes prioritizing a speed improvement far more effective than applying every possible optimization technique at once, several of which won't move the needle for a given site's actual bottleneck.
Server response time: the foundation everything else builds on
Before a browser can render anything, it has to receive the first byte of the response — and every other optimization on this list only affects what happens after that point. A slow server response time (high "time to first byte") puts a floor under how fast a page can possibly feel, regardless of how optimized everything downstream is. This is affected by server-side application performance, database query efficiency, and the underlying hosting infrastructure itself — sufficient CPU, RAM and fast storage, covered in more depth further below. A site can have perfectly optimized images and no render-blocking scripts and still feel slow if the server itself takes a second or more just to start responding.
Caching: not repeating work that's already been done
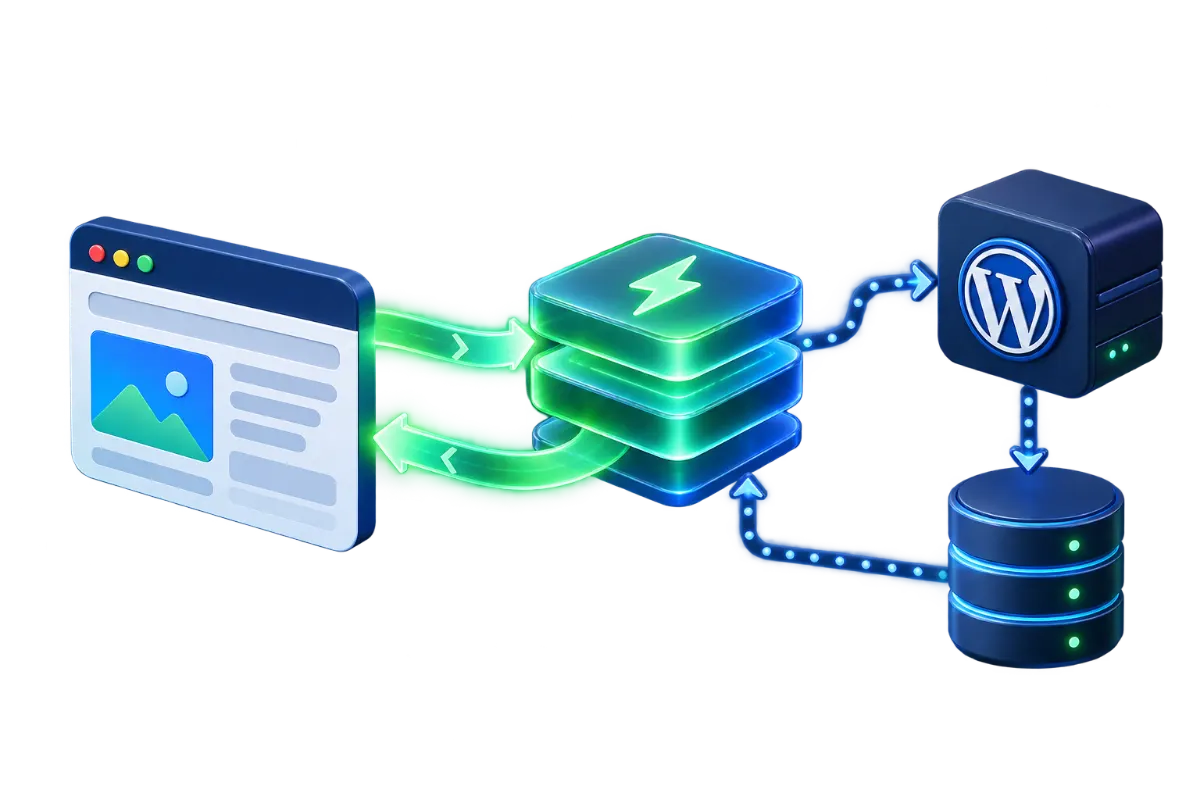
Caching stores the result of expensive work — a rendered page, a database query result, a computed value — so subsequent requests can reuse it instead of redoing it. This is frequently the single highest-leverage speed improvement available for a typical CMS-driven business site, because most pages don't need to be regenerated from scratch on every single visit; the content is the same for most visitors most of the time. Page-level caching, object caching for database queries, and browser caching for static assets (so a returning visitor doesn't re-download files that haven't changed) each address a different layer, and a site missing any one of them is leaving a proportionally large improvement unclaimed. If the site in question runs WordPress specifically, see How to Speed Up a WordPress Website Without Breaking It for CMS-specific caching steps and the mistakes to avoid when enabling them.
Images and asset weight
Images are typically the largest single contributor to total page weight, and an oversized, uncompressed, or wrongly-formatted hero image is one of the most common causes of a slow-feeling page load. Serving images in a modern format, compressed appropriately for the display size actually needed (not the original upload resolution), and only loading below-the-fold images once a visitor scrolls near them (lazy loading) each reduce how much data has to be transferred and decoded before a page feels complete. This is also the factor most directly tied to Largest Contentful Paint — see Core Web Vitals for Business Websites for how that specific metric is measured and diagnosed.
Render-blocking resources
A browser can't start painting a page until it's processed the CSS and, in many configurations, certain JavaScript in the page head — resources that block rendering delay the point at which anything becomes visible at all, even if the underlying content itself would otherwise be ready quickly. Deferring non-critical CSS and JavaScript, and inlining only the small amount of CSS actually needed to render the visible portion of the page immediately, reduces this delay directly. This is a case where the fix is specifically about *when* resources load, not how large they are — a small render-blocking script can cause a more noticeable delay than a larger one that's properly deferred.
Third-party scripts
Analytics tags, chat widgets, advertising scripts and social embeds are collectively one of the most common and most overlooked sources of slowdown, because each one is individually small enough to seem harmless while the cumulative effect of several loaded on every page is not. Each third-party script adds its own network request, its own execution time on the browser's main thread, and, for some, its own additional dependent requests it triggers after loading. Auditing which third-party scripts are actually necessary, and deferring or lazy-loading the ones that aren't required for the initial page experience, is frequently a bigger win than it initially appears, precisely because it's the category most likely to be present on every single page of a site without anyone specifically deciding to add that much cumulative weight.
A prioritization example
A business site measures poorly on LCP and reasonably on INP and CLS. Rather than working through the full generic optimization list, the targeted approach starts with the causes specifically tied to LCP: time to first byte turns out to be fast, ruling out server response time as the cause, but the hero image on the homepage is a 3MB unoptimized JPEG loading before any other visible content — compressing and correctly sizing that single image, and setting it to load with priority, resolves the majority of the LCP problem on its own. A second, smaller pass addresses a render-blocking analytics script in the page head by deferring it, closing most of the remaining gap. Two targeted changes, driven by what the measurement actually identified, accomplish more than a broad pass applying every technique on the full list — including several, like third-party script auditing beyond that one analytics tag, that weren't actually contributing meaningfully to this specific site's problem.
Measuring what actually matters
The practical way to prioritize among these factors for a specific site is to measure first rather than guessing which applies. Core Web Vitals — LCP, INP and CLS — each point toward a different category from the list above: a slow LCP usually traces back to server response time or unoptimized images; a poor INP usually traces back to heavy JavaScript, often from third-party scripts; a poor CLS usually traces back to images or embedded content without reserved space. Measuring which specific metric is actually failing, rather than applying every optimization on this list uniformly, identifies which factor is the real bottleneck for a given site and makes the fix targeted rather than a broad, unfocused effort.
Why hosting sets the ceiling for every other optimization
It's worth closing on the point the list opened with, because it's the one most often skipped: every optimization above — caching, image compression, deferred scripts — improves how efficiently a page uses the resources available to it, but none of them raise the underlying ceiling those resources impose. A server that's short on CPU will apply caching logic slower than a well-resourced one; a server with slow storage will write cache entries and query results slower regardless of how well the caching strategy itself is designed. This is why a site that's applied every front-end optimization on this list and still feels sluggish is worth checking at the hosting layer specifically — sufficient CPU and RAM for the application's actual load, and fast, NVMe-class storage for anything that touches disk, covered in more detail in How CPU, RAM and Storage Affect Server Performance. Front-end optimization and adequate hosting aren't alternatives to each other; they address different layers of the same problem, and skipping either one leaves real, available speed on the table. A site built well on undersized hosting, and a site built poorly on excellent hosting, tend to land in roughly the same disappointing place for a visitor who has no visibility into which layer is actually at fault — which is exactly why both layers need attention rather than treating one as a substitute for the other.