Server uptime is normally expressed as a percentage of time a server or service was reachable and responding over some period — a month, a year. The percentage is simple to state and easy to misread, because it hides two things that matter just as much as the number itself: how the measurement was actually taken, and what counts as "down" in the first place.
How uptime is actually measured
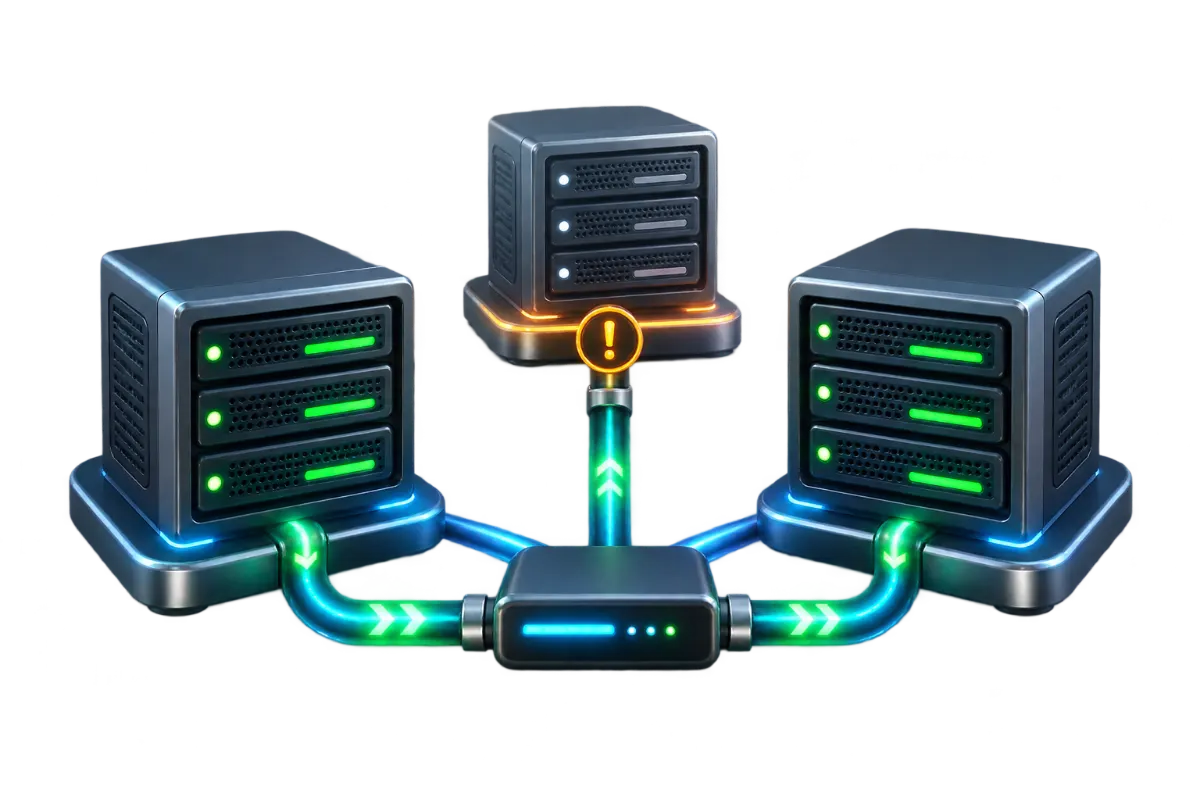
Uptime monitoring works by sending periodic checks to a server — an HTTP request, a ping, a port connection attempt — at some fixed interval, and recording whether each check succeeded or failed. The reported uptime percentage is essentially (successful checks minus failed checks) divided by total checks, over the measurement period. This means the check interval directly affects what gets measured: a monitor checking once every 5 minutes can only ever detect outages in 5-minute resolution — a server that goes down and recovers within 2 minutes might never register as a failed check at all, while a monitor checking every 10 seconds would catch that same brief outage. Two monitoring setups watching the exact same server can report different uptime percentages purely because of how often they checked, which is why the measurement method is part of what the number means, not a footnote to it. Where the check comes from matters as much as how often it runs: a monitor probing from a single location only ever sees the path between that one point and the server, and a regional network problem, a routing issue, or an outage affecting just one part of the internet can make a server unreachable to real visitors in that region while a monitor checking from somewhere else reports perfect uptime the entire time. See Website Monitoring Explained for how checking from multiple locations closes that specific blind spot.
What "the nines" mean in practical terms
Uptime is often described in terms of how many nines it has, and the practical difference between them is easiest to see converted into actual downtime over a year:
| Uptime | Downtime per year | Downtime per month |
|---|---|---|
| 99% | ~3.65 days | ~7.3 hours |
| 99.9% ("three nines") | ~8.76 hours | ~43.8 minutes |
| 99.95% | ~4.38 hours | ~21.9 minutes |
| 99.99% ("four nines") | ~52.6 minutes | ~4.38 minutes |
The jump between each tier is larger than it looks written as a percentage — going from 99% to 99.9% cuts annual downtime from roughly three and a half days to under nine hours, and 99.9% to 99.99% cuts it further to under an hour. Each additional nine is meaningfully harder and more expensive to achieve in practice, which is why it's worth being precise about which tier actually matters for a given site rather than treating "more nines" as free.
Common causes of downtime
Downtime isn't exclusively, or even mostly, a hardware failure event. Common causes include planned maintenance windows (software updates, hardware replacement) that weren't communicated as downtime but register as one in a monitor's eyes, misconfiguration deployed by mistake, resource exhaustion (a server running out of memory or disk space under unexpected load), network-level issues upstream of the server itself, and DDoS or traffic spikes overwhelming available capacity. Not all downtime is the server's own fault, either — a DNS misconfiguration or an upstream network outage can make a perfectly healthy server unreachable, which a monitoring check reports identically to an actual server failure, since from the outside both look the same: no response. This is part of why root-causing an outage after the fact matters as much as detecting it in the first place — a server that was technically healthy throughout an incident caused by an upstream DNS or network problem needs a different fix than one that actually crashed, even though both show up as identical downtime in a monitoring report. Hardware failure specifically — a failed disk, memory error, or other physical component issue — tends to be the least common cause on well-maintained infrastructure relative to the other causes listed here, if only because it's the one category modern redundant hardware and virtualization layers are specifically designed to minimize, while configuration mistakes and resource exhaustion remain squarely a matter of operational practice rather than hardware reliability.
Uptime per server vs. uptime per service
"The server is up" and "the website is working" are not always the same fact, which is a distinction worth being precise about. A server can be fully reachable and responding to a basic connectivity check — the operating system is running, the network connection is healthy — while the specific application running on it (the web server process, the database, a particular service) has crashed or hung. A monitor that only checks whether the server responds to a ping has no visibility into that failure at all, because from a pure network standpoint the server is perfectly healthy. This is why meaningful uptime monitoring checks the actual service that matters — a successful HTTP response from the website itself, not just a reachable IP address — and why a single server hosting multiple independent services (a website and a separate API, for instance) can have each one measured and reported on separately, since one going down doesn't necessarily mean the others did too.
What a monitoring tool actually checks
A basic uptime monitor typically checks for a successful connection and response within a set timeout — confirming the server is reachable and responding at all. More thorough monitoring checks for a specific expected response (a particular HTTP status code, specific text in the response body), which catches a server that's technically responding but serving an error page or a broken state that a simple ping-style check would miss entirely. See Website Monitoring Explained for how uptime checks fit alongside performance and alert monitoring more broadly, rather than as the only thing worth watching.
Uptime figures vs. a service level agreement
It's worth being explicit about one distinction: a general technical figure like "99.9% is roughly 8.76 hours of downtime a year" is just arithmetic, not a commitment from any specific provider. Any actual guarantee a hosting provider makes about uptime — including what counts as qualifying downtime, how it's measured, and what remedy applies if it's missed — lives in that provider's own service level agreement, which is a contractual document specific to that provider and plan, not a universal technical standard. Treat the percentages above as a way to understand what a given number means in hours, not as a representation of what any particular hosting plan guarantees. When comparing providers or plans, the detail worth reading in an actual SLA is rarely the headline percentage itself — it's the definition of what counts as downtime (does scheduled maintenance count against the figure, or is it excluded entirely), how that downtime gets measured and by whom, and what remedy, if any, applies when the commitment is missed. Two plans advertising the same headline percentage can differ substantially once those details are accounted for.
The practical takeaway
Two practical habits matter more than chasing a specific nines figure: knowing how your own monitoring measures uptime (check interval and what counts as a failure) so the number you're looking at actually means what you think it means, and treating uptime as one signal among several rather than the only measure of whether a site is healthy — a server that's technically "up" by a ping check while serving a broken page to every visitor is a failure a narrow uptime definition won't catch. Chasing an extra nine of uptime is rarely the highest-value thing to invest in before a site has solid monitoring, a tested backup and restore process, and a baseline understanding of what typically causes its own downtime — those three things determine how quickly a real incident gets noticed and resolved, which matters more in practice than a theoretical ceiling a well-run ordinary setup was unlikely to hit anyway.